M.Eng. in Artificial Intelligence · Science Tokyo
I’m a speech and audio ML researcher with a Master of Engineering in Artificial Intelligence from the Institute of Science Tokyo. My research focuses on speech separation, neural audio codecs, and robust speech recognition.
Outside research, I enjoy photography and am a cinematography enthusiast. You can find my photos and videos in Photo.
News
2026
I presented my paper at Interspeech 2026.
I was selected to receive the diploma on behalf of all students in the Department of Computer Science, School of Computing, at graduation.
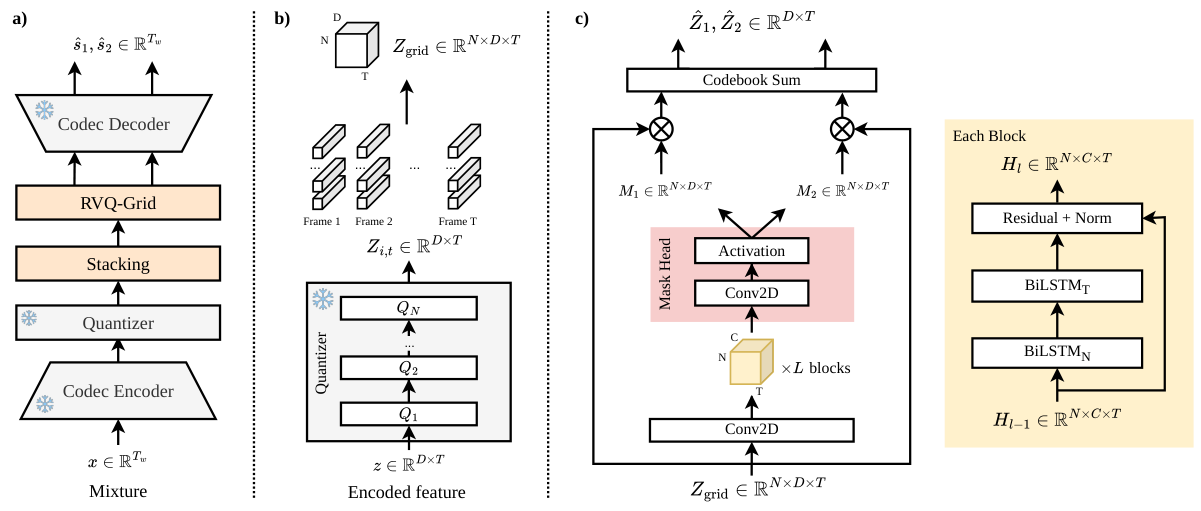
My paper (RVQ-Grid) was accepted at Interspeech 2026.
I presented our work on cross-layer RVQ processing at 音学シンポジウム.
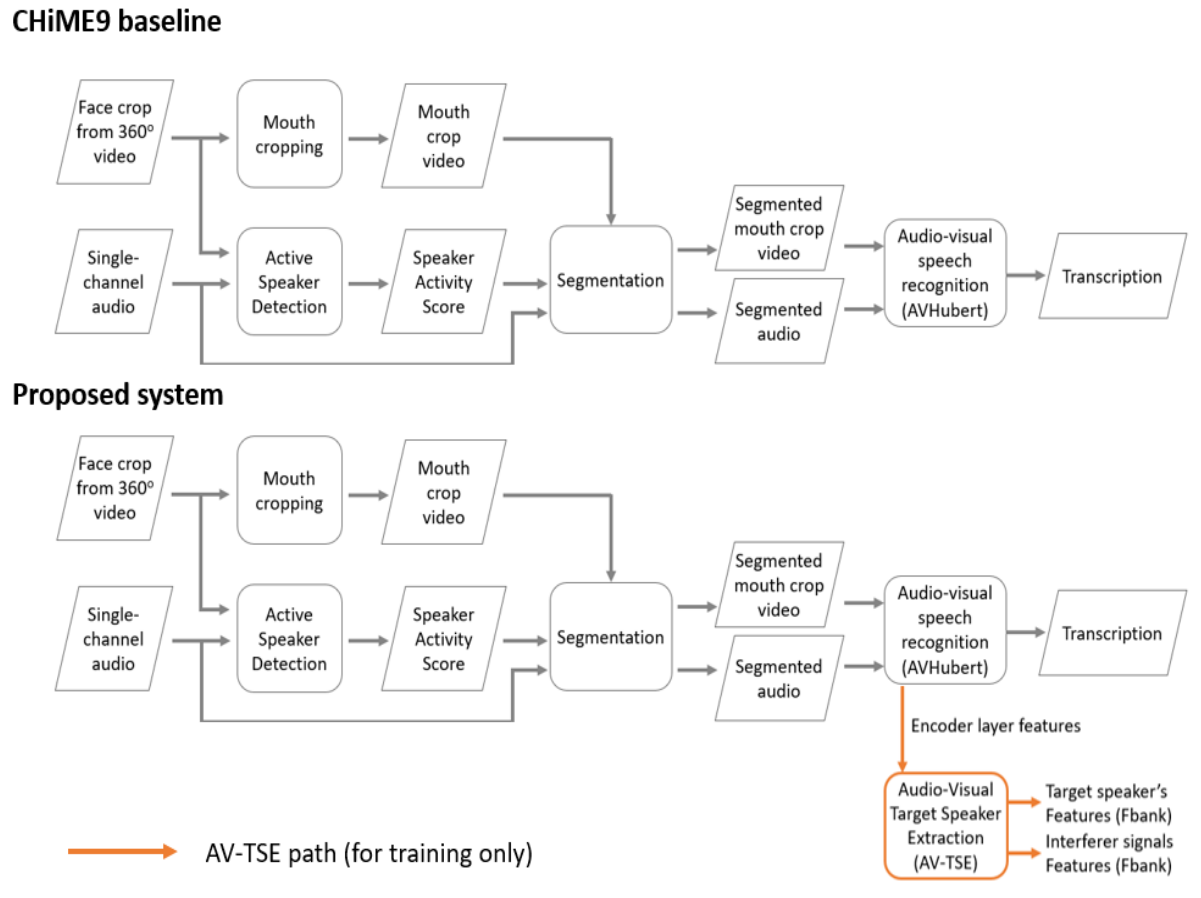
Our Science Tokyo MCoRec system paper appeared in the CHiME 2026 proceedings.
2025
I joined a research collaboration between Shinoda Laboratory and NEC’s research lab in Tokyo.
2024
I started my M.Eng. in Artificial Intelligence at Science Tokyo.
2021
I joined LINE Technology Vietnam as a software engineer.
2020
I graduated from USTH and joined ABIVIN as a software engineer.
Publication
Cross-layer recurrent processing of Residual Vector Quantization layers for Audio Codec-based speech separation
IEICE Technical Report · SP2026-23 · pp. 125–129
Cross-layer recurrent processing preserves the coarse-to-fine structure of RVQ layers for codec-based speech separation.
Education
M.Eng. in Artificial Intelligence
B.Sc. in Information and Communication Technology
Experience
Research Assistant
Software Engineer
Software Engineer
Skills
- Research
- Engineering
- Languages
Awards
LINE Engineering Culture winner
LINE
LINE Technology Vietnam Awards winner
LINE Technology Vietnam
Excellent Student Scholarship (Fully Funded)
University of Science and Technology of Hanoi